The pipeline
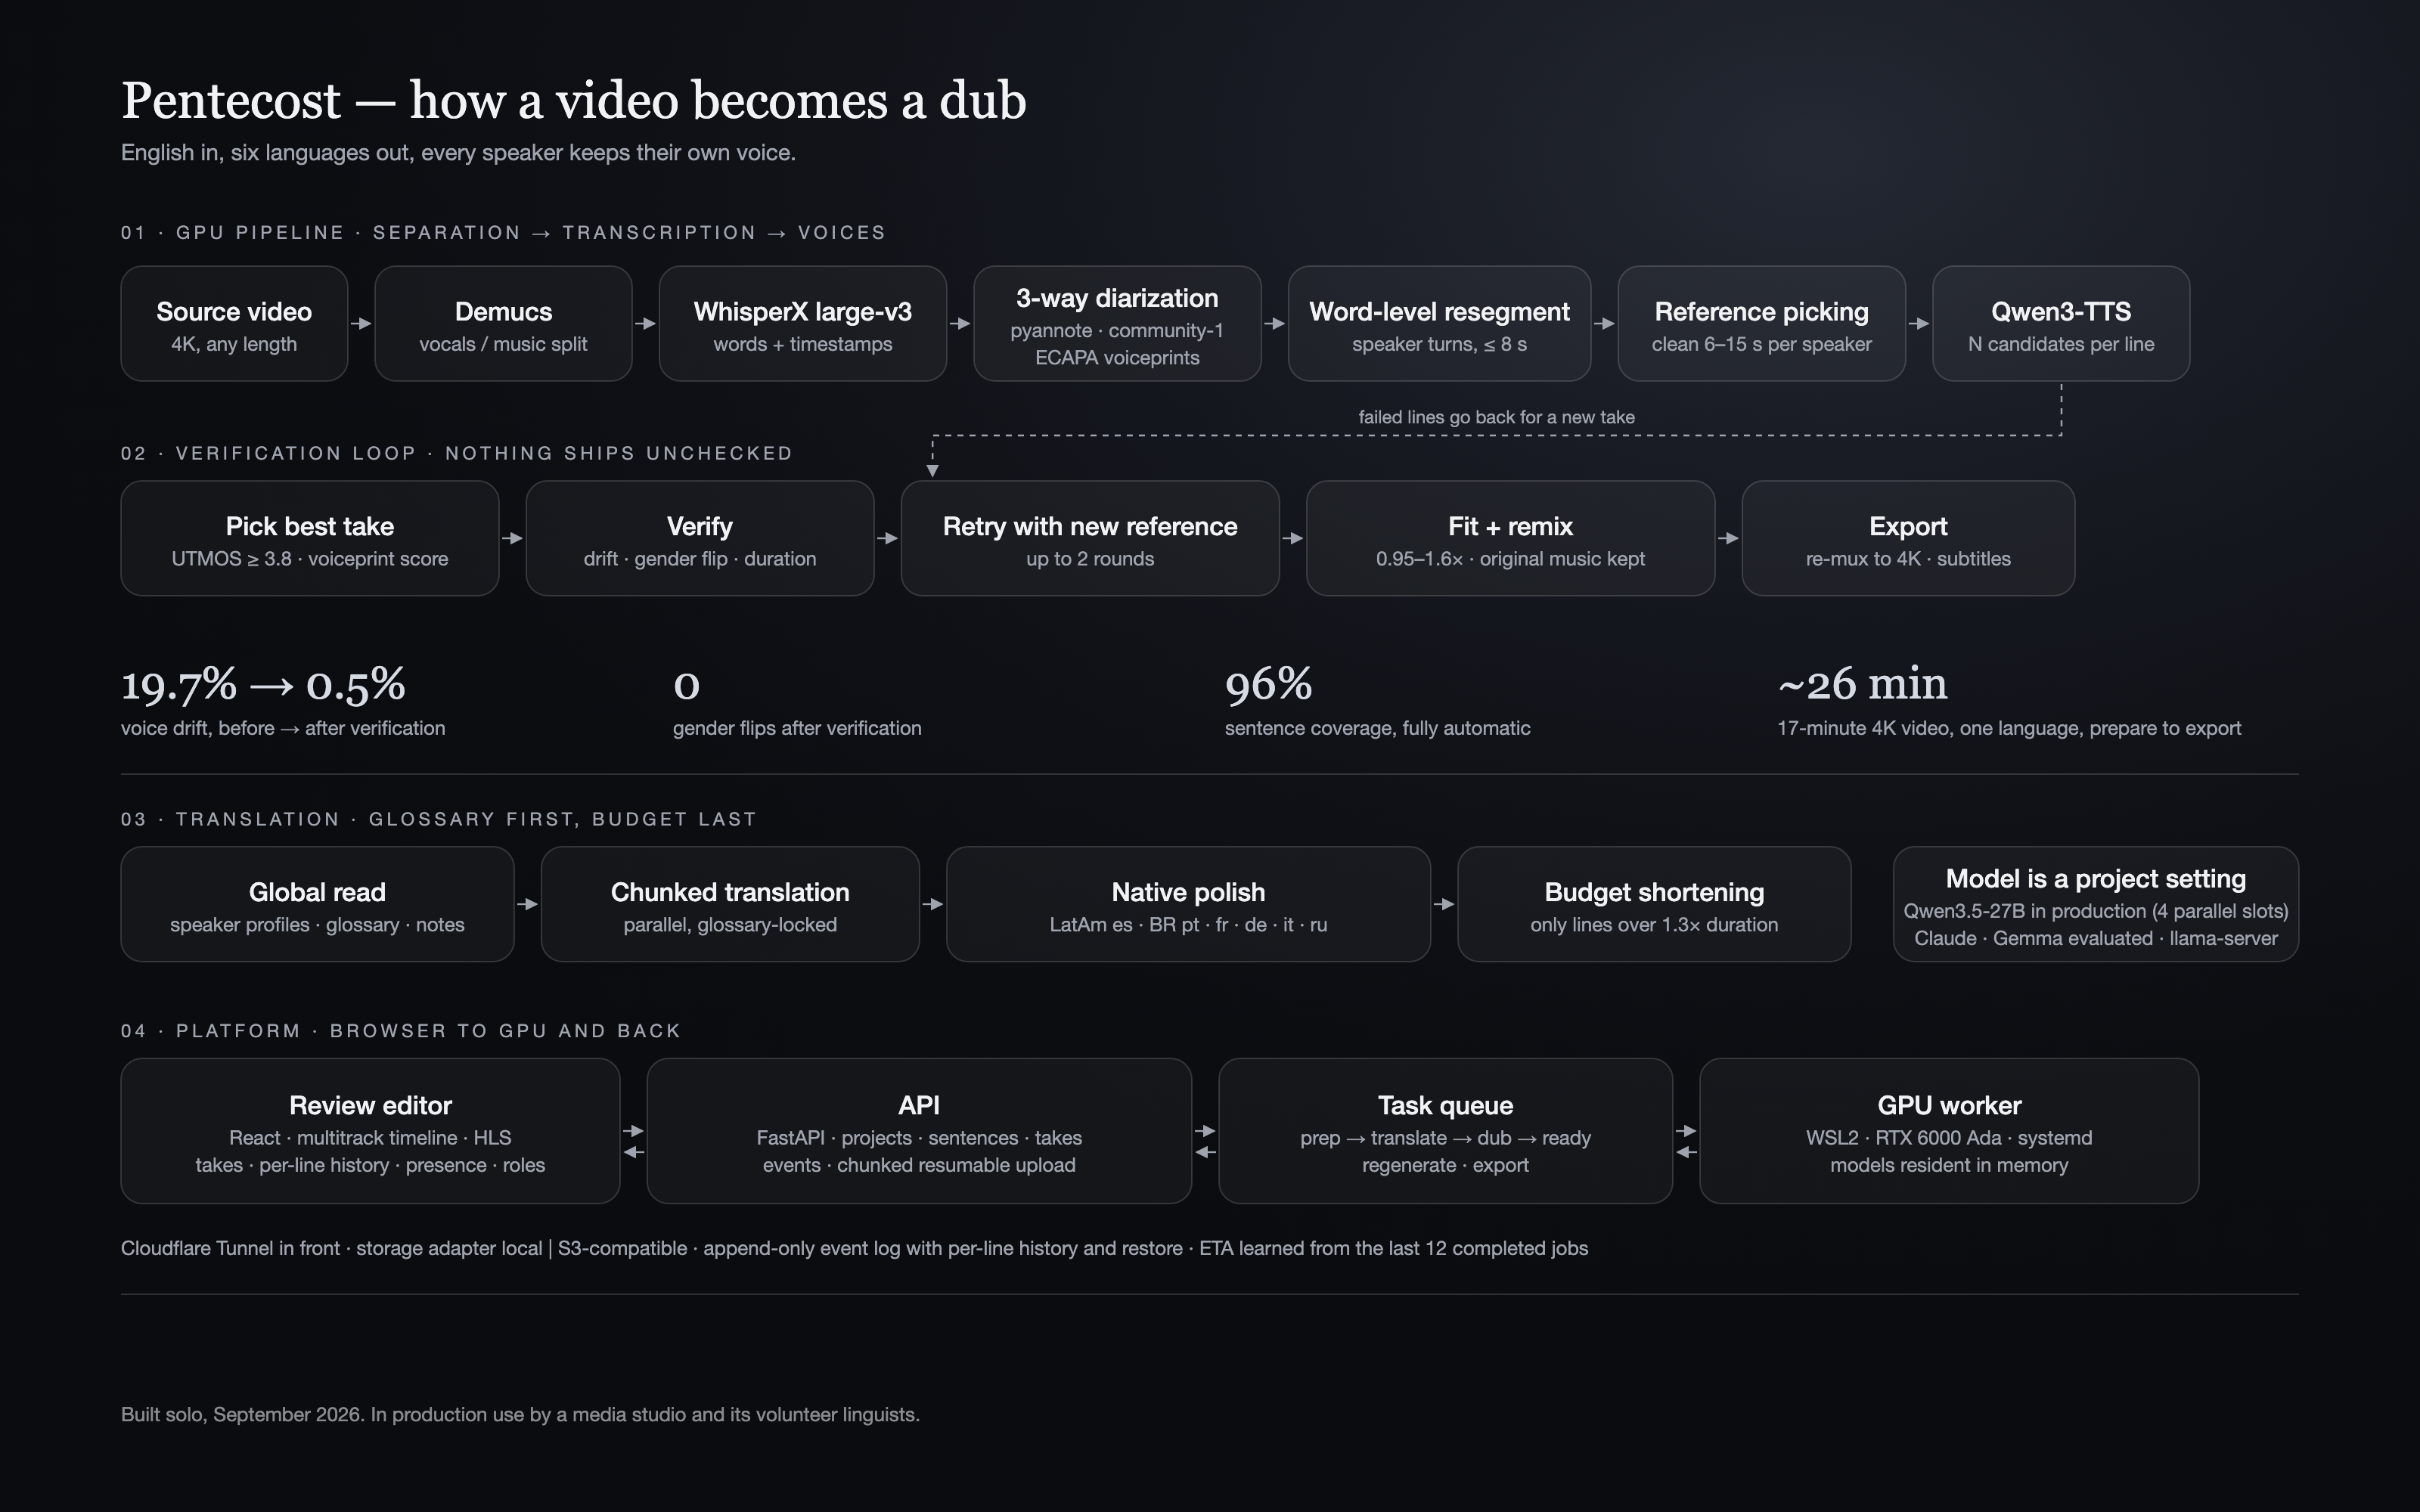
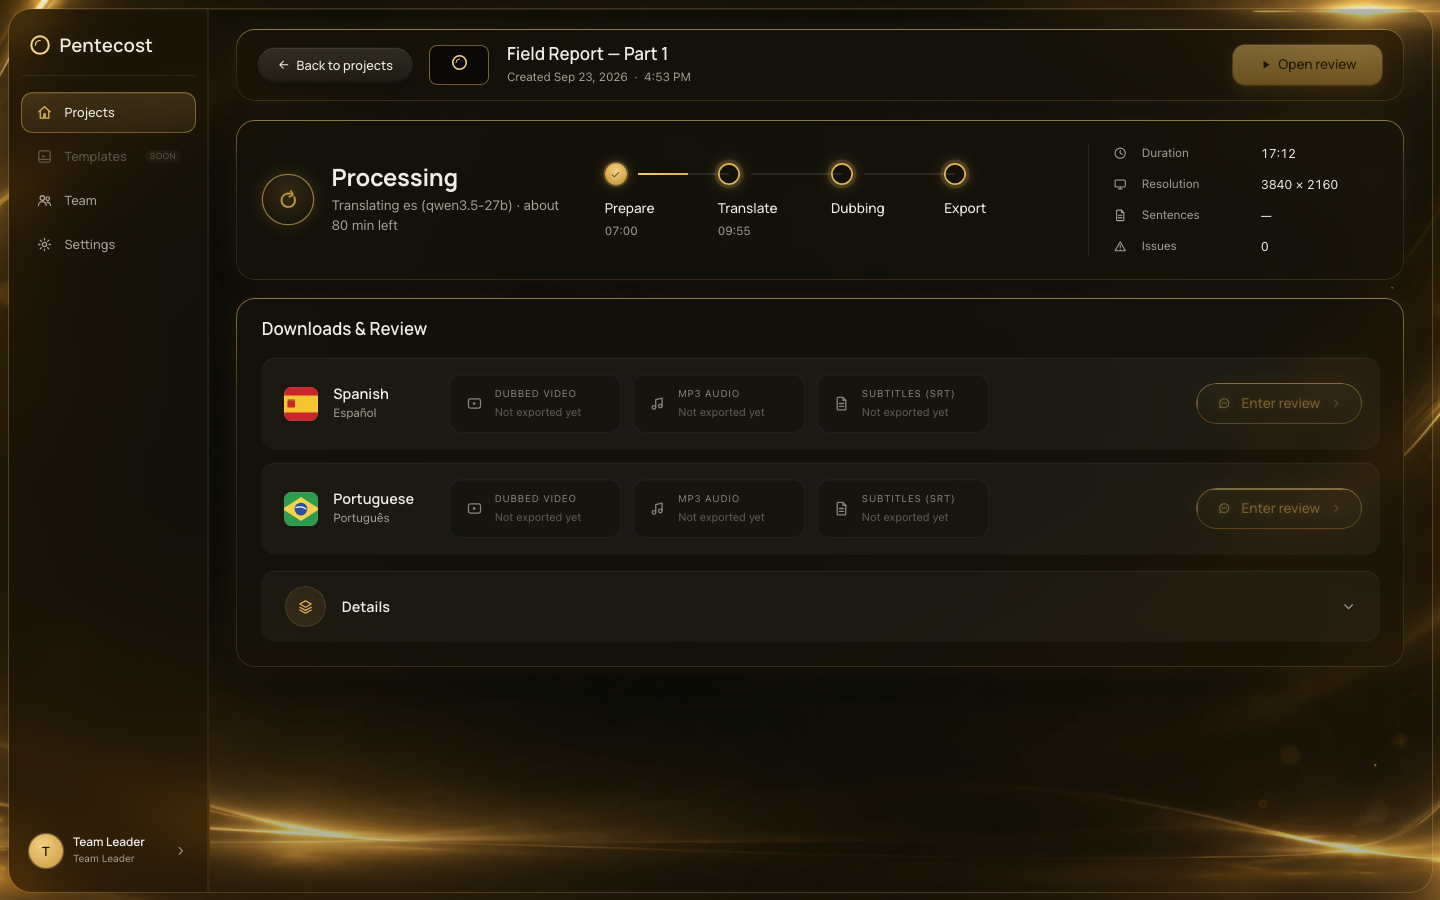
Demucs splits vocals from music; WhisperX transcribes with word timestamps; pyannote diarizes with a second model checking the speaker count and ECAPA voiceprints correcting labels. Sentences are re-cut at speaker turns, a clean reference clip is chosen per speaker, and Qwen3-TTS voices each line several times. Takes pass a naturalness gate (UTMOS ≥ 3.8), a voiceprint match, gender and duration checks, and failed lines retry with new references. Lines are fitted to their slots, mixed with the original music, and muxed back into the 4K source.
Translation
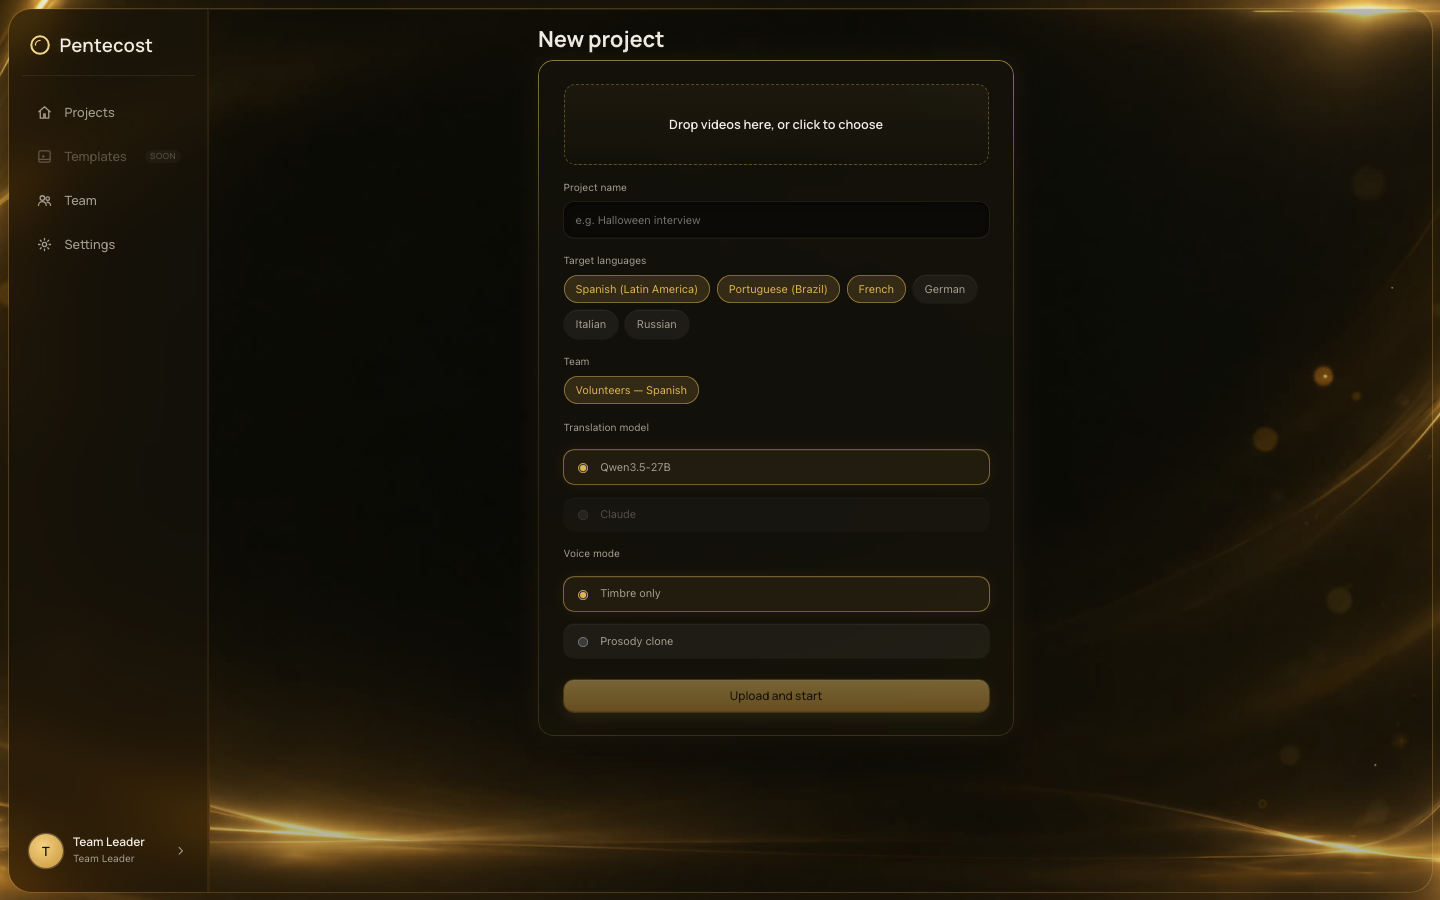
Three passes, not one. A global read produces the programme type, register, speaker profiles and a glossary; chunked translation works under a per-line character budget derived from each line's duration; a native-editor pass polishes; only lines still over budget get shortened. Six target languages with dialect rules. Production runs Qwen3.5-27B locally on llama.cpp with four parallel slots, after native-speaker blind comparisons against Claude and Gemma: roughly $0.50 of GPU time per language per video instead of $7–11 in API calls.
The review console
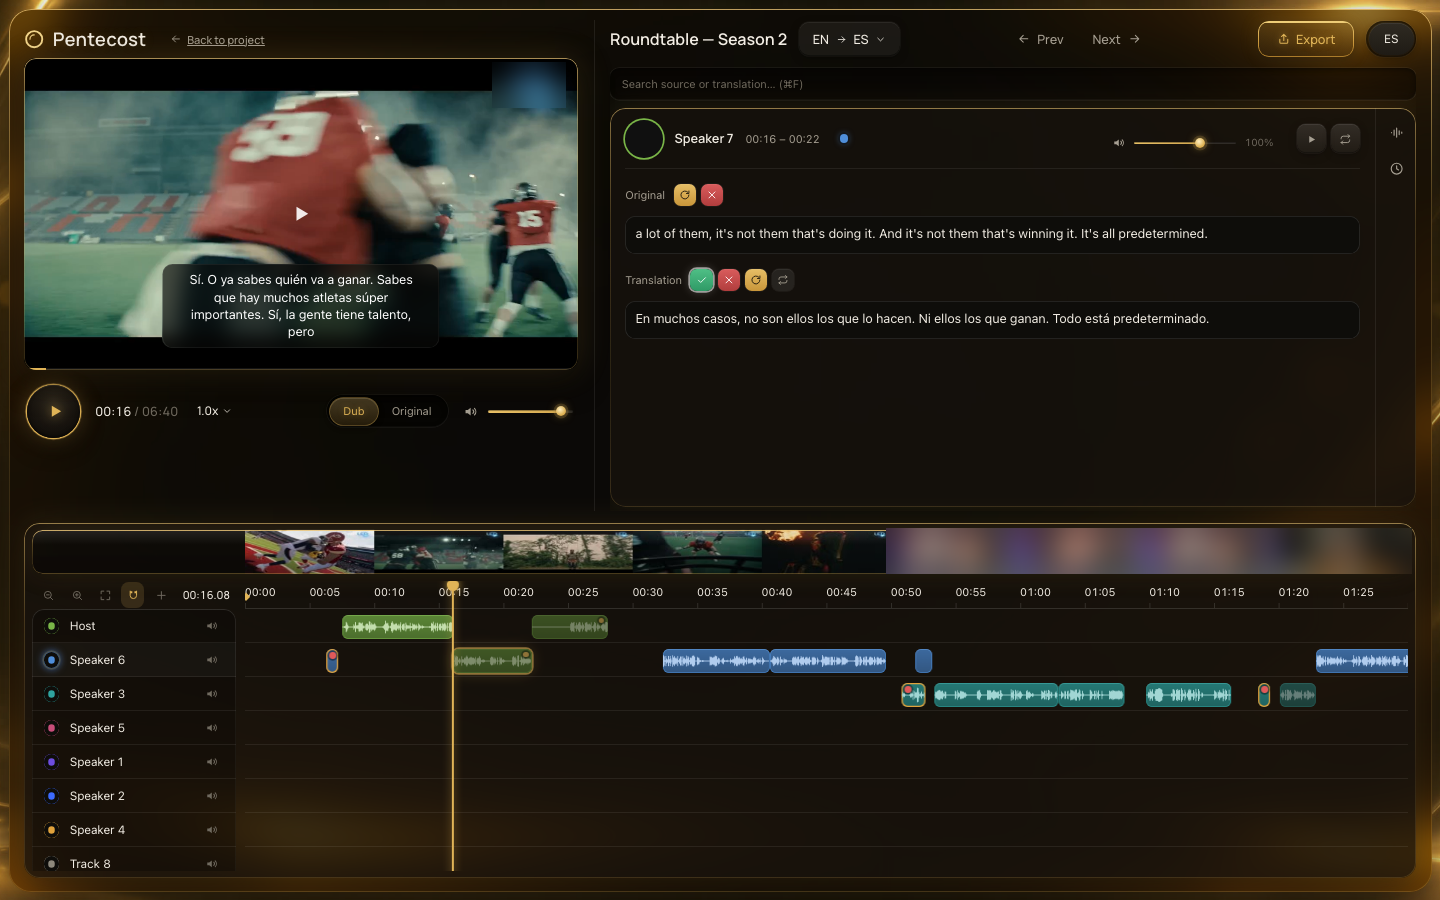
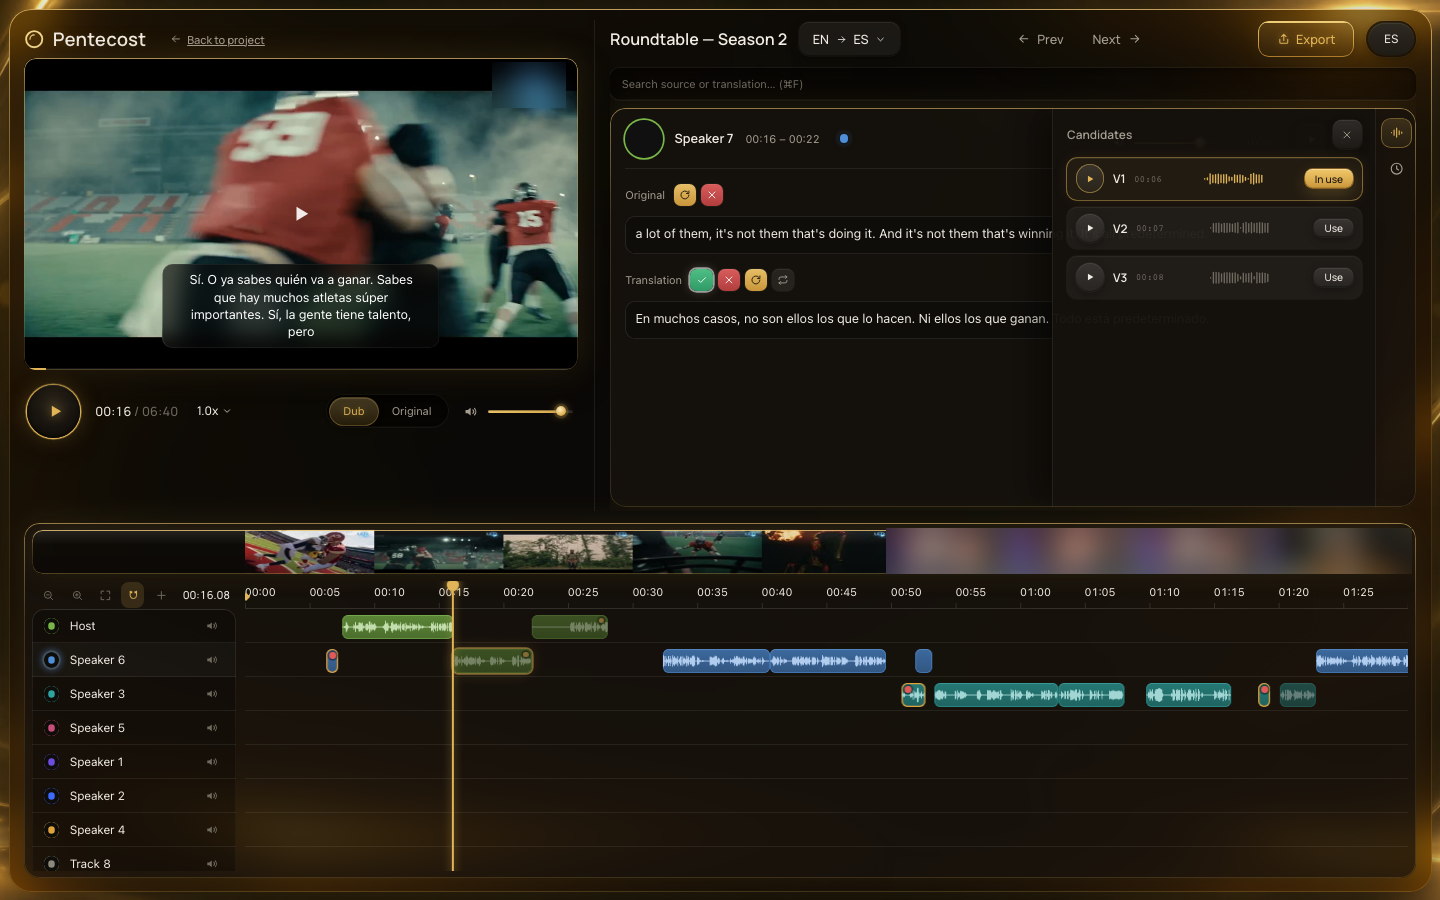
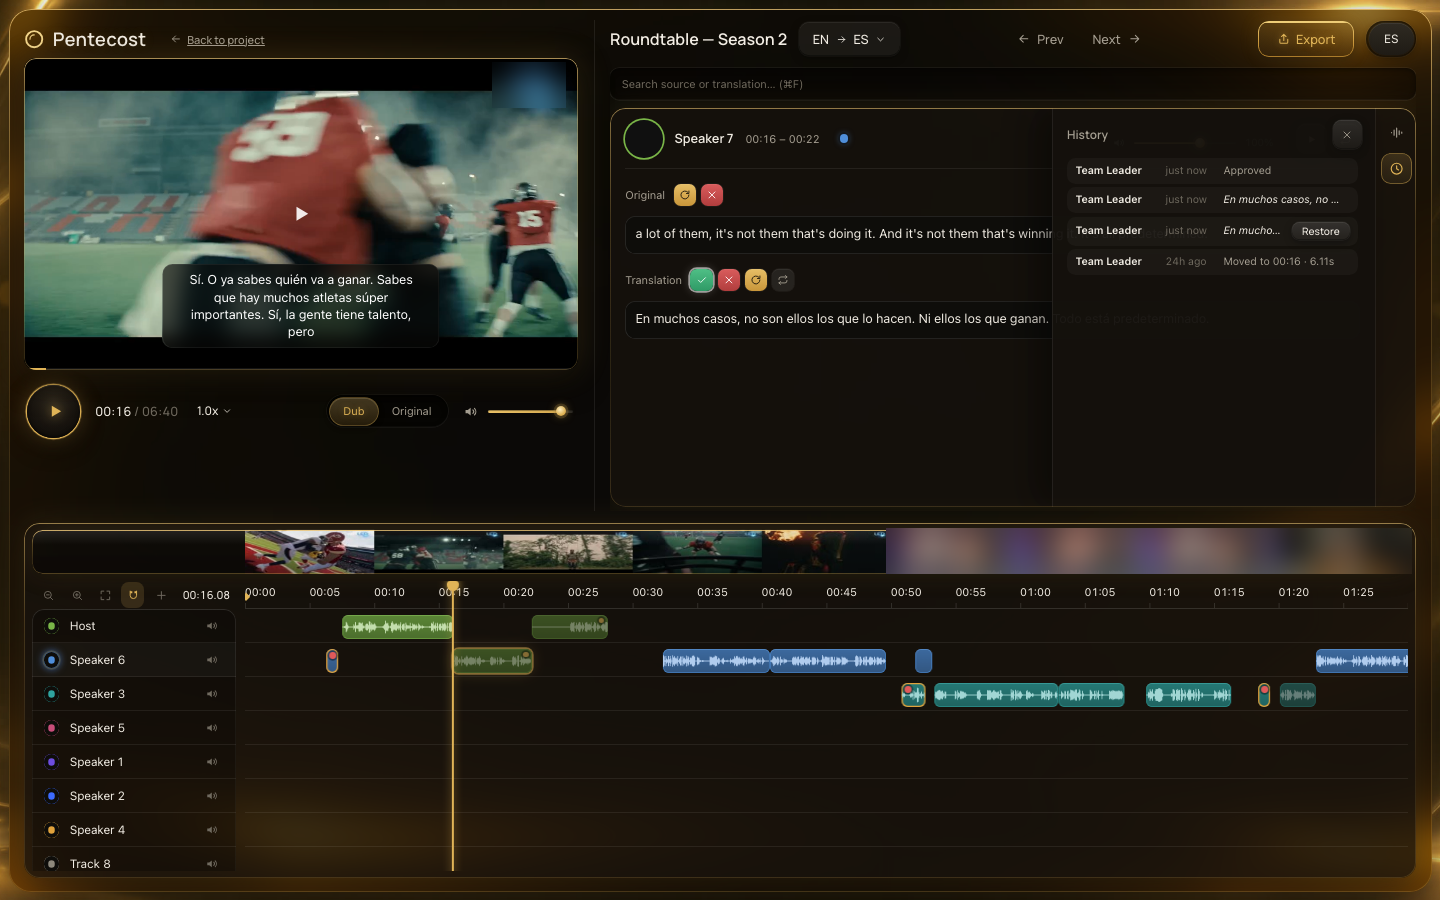
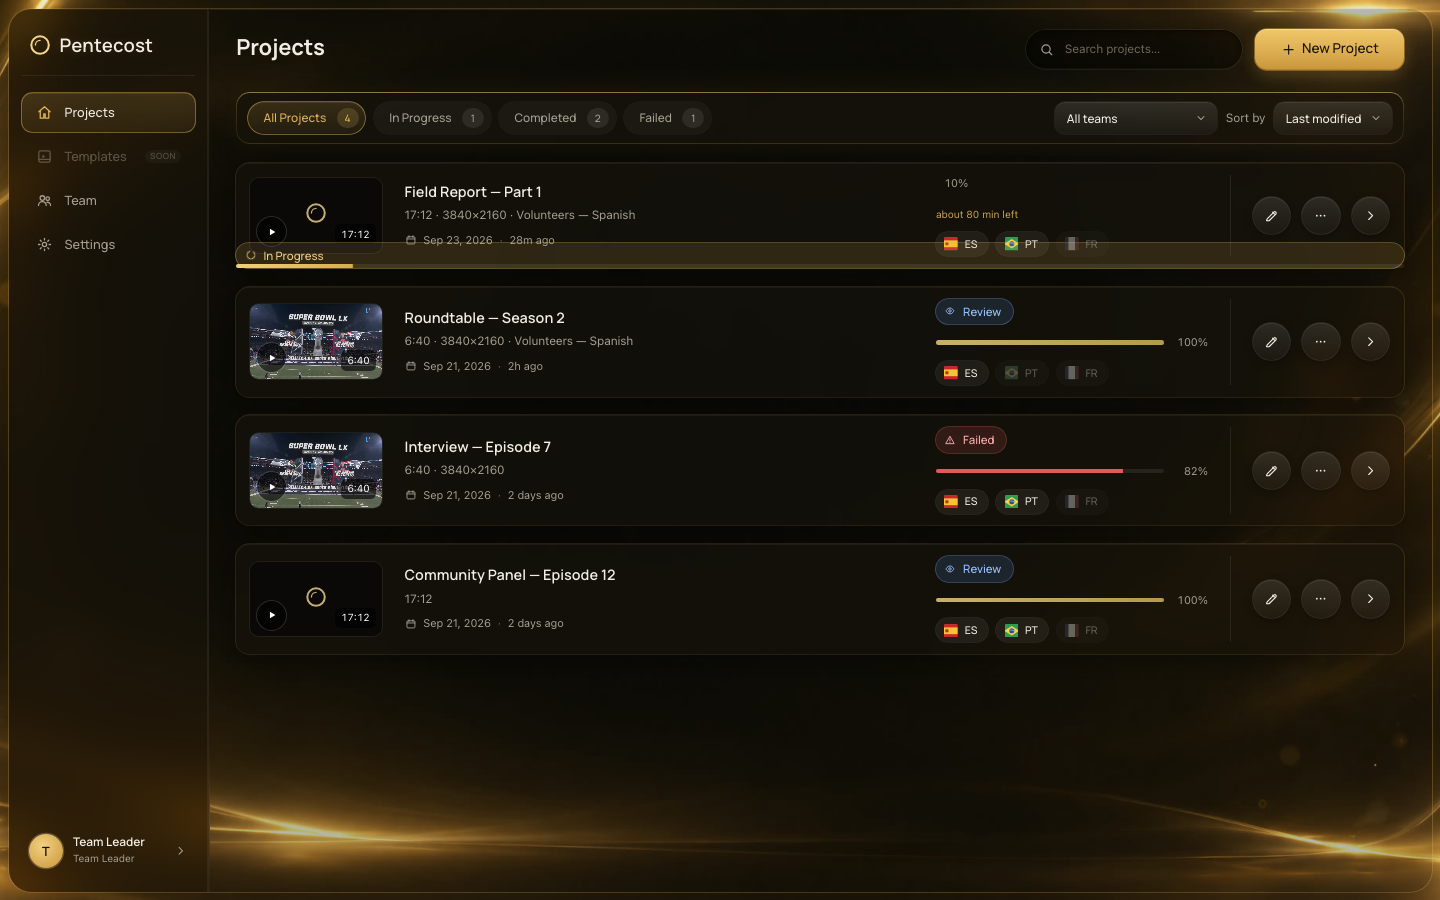
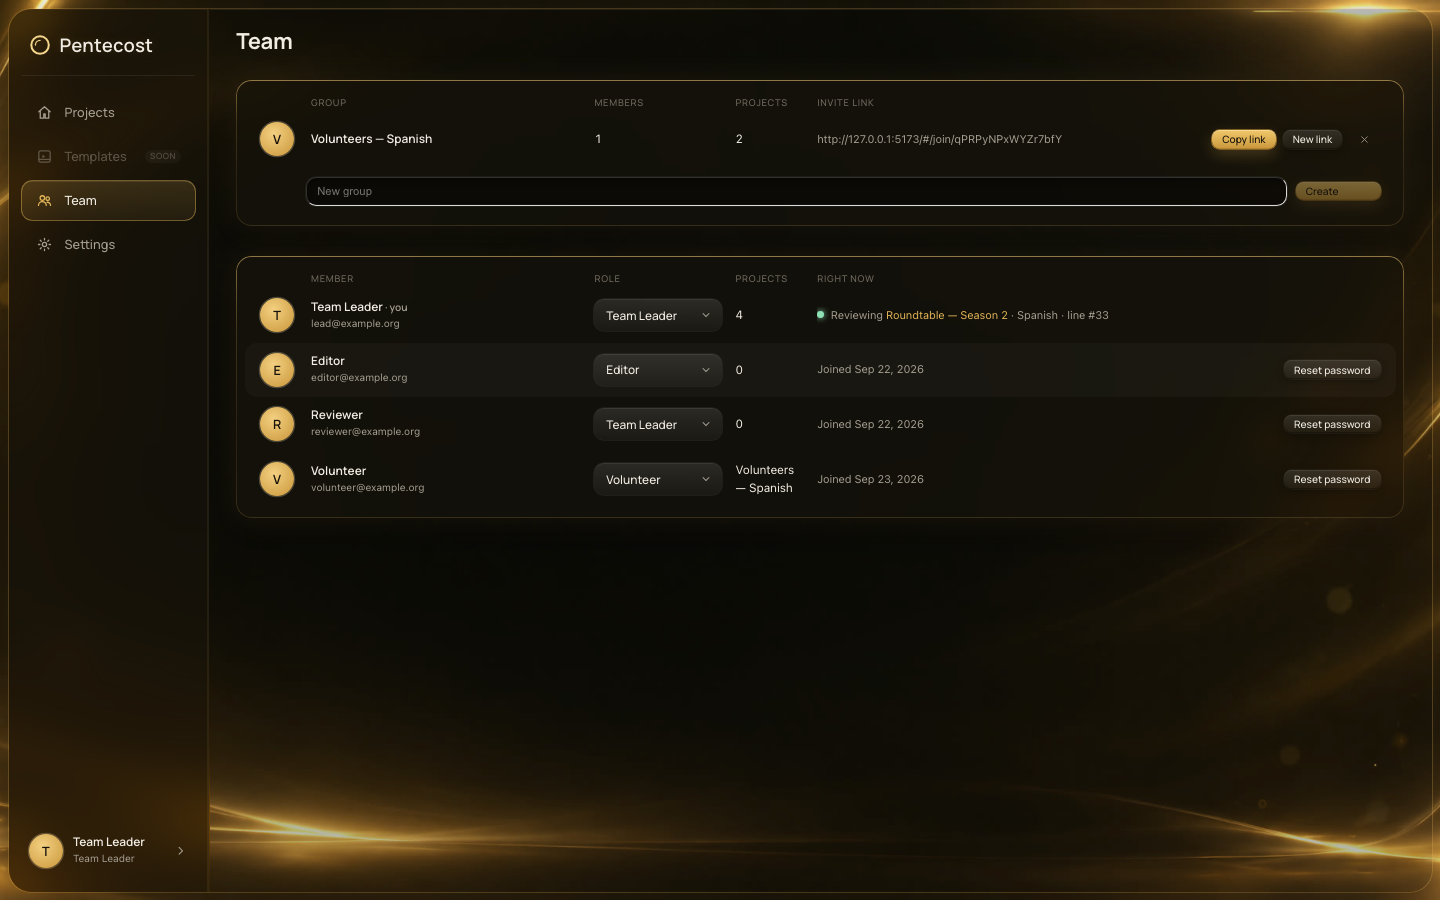
One timeline lane per detected speaker, waveforms on every clip, drag, trim, snap and lane moves with editing-software overlap rules. Each line shows the original and the translation, both editable; fixing a misheard word re-translates that line in every language. A candidates drawer auditions three takes; a history drawer shows who changed what and restores any version. Reviewers see each other's presence on a line. Export gives a re-mixed video, MP3, SRT, VTT and a markers CSV. Roles and invite links keep volunteers to their own group's projects.
What it took to make voices stay put
The first dub put the wrong voice on 19.7% of lines with 14 gender flips. Diarization looked guilty, but three independent speaker systems agreed; the real causes were reference clips contaminated by another speaker's interjection and TTS drift on short lines. Choosing references nearest each speaker's voiceprint centroid, verifying every synthesized take against its speaker, and retrying with alternates brought drift to 0.5% and gender flips to zero. That loop is now the pipeline's spine.
Engineering notes
Three weeks, 63 commits, 22 API tests plus Playwright acceptance scripts, seven design docs. Chunked resumable upload with the parts on disk as the source of truth after a race lost parts. Media served as single-file fMP4 HLS after Chrome's progressive loading stalled behind Cloudflare on HTTP/2. Audio and video kept in sync across output latency with a one-time offset and rate trims, Safari-safe. Four systemd services inside WSL2 on a single RTX 6000 Ada workstation, kept alive without a desktop session, nightly backups, an append-only event log behind every edit.